Star Trek Bots
Problem or curiosity
Could a translation model be misused into becoming a tiny television writer?
In 2017, before chat interfaces were the default shape of AI demos, I was playing with Google's TensorFlow NMT project. It was built for machine translation, using an LSTM sequence-to-sequence architecture. The experiment was simple: instead of translating French to English, let a window of Star Trek: The Next Generation script text "translate" into the next bit of script.
The source code implemented that as a 100-word input window and a 15-word output target. It was not a general chatbot in the modern sense. It was a deliberately odd reuse of translation tooling: previous script context in, next script fragment out.
What was built
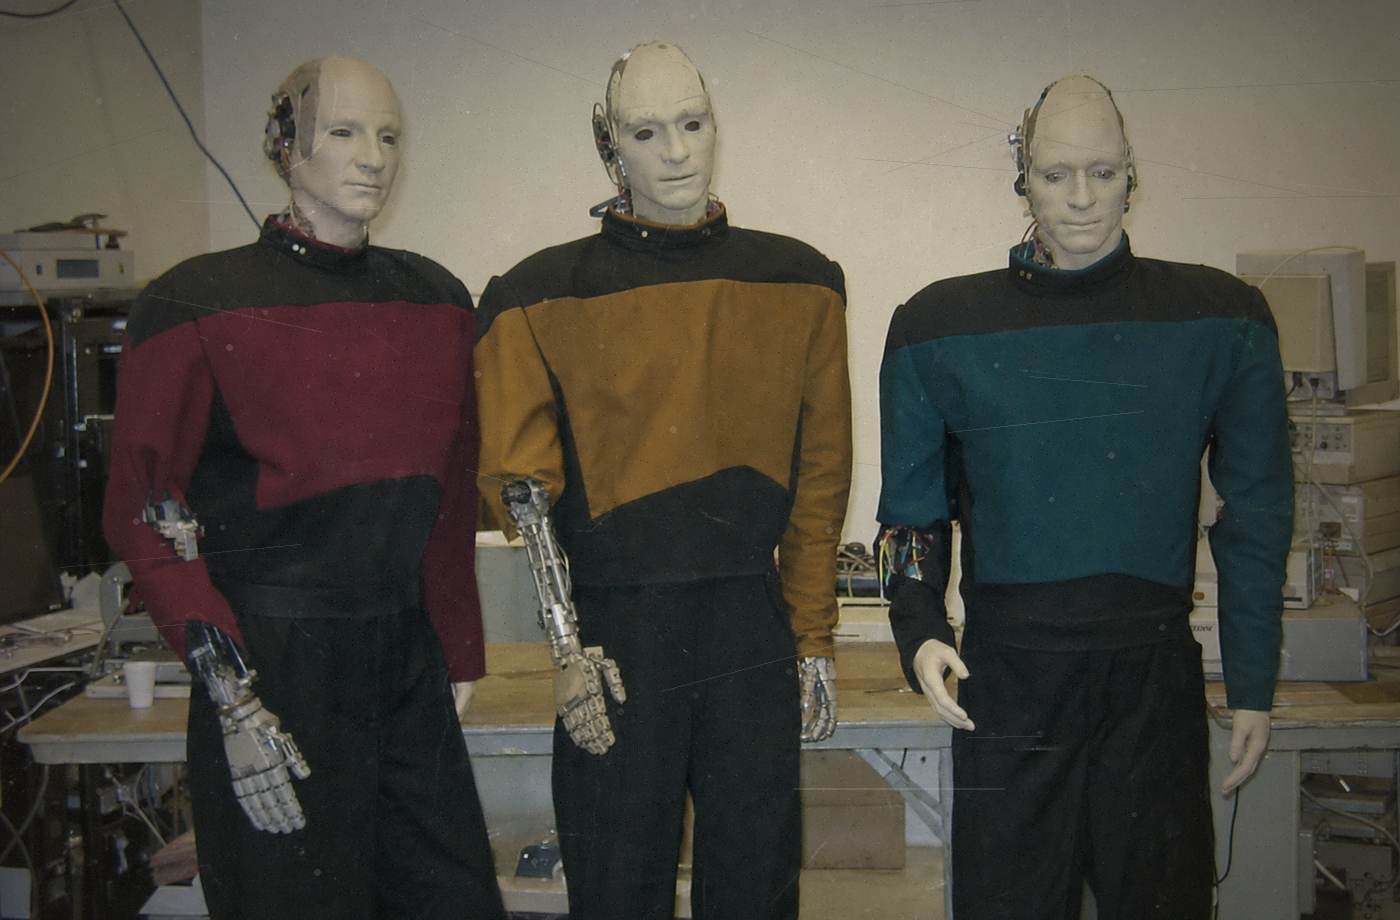
The first version trained an NMT model on Star Trek scripts, then connected the model to Twitter accounts including BotPicard, BotTroi, BotLaforge, BotRiker, BotWorf, CmdrDataBot, and ST_NarratorBot.
The bots reconstructed a thread into script-like dialogue, assigned human players to unused characters, generated the next line, and tweeted it back into the conversation. There were small bits of product thinking hiding inside the joke: duplicate-status avoidance, human handoff, narrator behavior, character assignment, and a rule that kept conversations from running away forever.
The backend ran on OpenWhisk. That infrastructure is long gone, so the live system no longer works. The code remains in rawkintrevo/startrek_chatbots.
In 2020, the work moved into startrekbots.com, a frontend site with archived chats and supporting Firebase pieces. That site was also powered by an OpenWhisk-backed generation path, so the interactive parts no longer work, but the archive still shows some of the old shape of the project.
In 2022, during a developer-relations consultancy for Arrikto around Kubeflow commercialization, I rebuilt the idea as a GPT-2 fine-tuning example: Startrek Plot Generator. That version lives in rawkintrevo/startrekplots, mostly as notebooks plus another OpenWhisk-serving path and a small React web UI.
What it proved
The useful part was not "a Star Trek bot can say Star Trek-ish things." The useful part was seeing how much product behavior sits around a model before it feels usable: thread reconstruction, prompt construction, identity, turn-taking, human fallback, rate limits, deployment choices, and archive surfaces.
It also caught a pattern that keeps recurring in agent work: a model can be clever in isolation and still need a surrounding protocol before people can actually collaborate with it.
What did not survive
OpenWhisk did not survive as a dependable backend choice for this artifact. IBM shut down the hosted path this work depended on, and both the Twitter bot version and later site-backed versions decayed with it. The old Twitter API assumptions are also historical now.
The generated text is an artifact of its era too: LSTM NMT first, then GPT-2 fine-tuning. Both are useful fossils, not current recommendations.
Why it matters
This is one of the earliest clean lines between my older ML tinkering and the current agent-workflow practice at aboriginal armadillo. It started as a playful abuse of a translation model, but it quickly became an exercise in orchestration: model output only became interesting after it was attached to roles, memory, channels, stop conditions, and human participation.
That lesson held up better than the stack did.